EOLE

Eole is an open language modeling toolkit built on PyTorch, originally spun off from OpenNMT-py. Train, fine-tune, evaluate, and serve encoder, decoder, and encoder-decoder models in a compact, modular codebase built for experimentation.
Use it for language generation, machine translation, neural translation scoring, vision and OCR, and speech recognition. Bring supported Hugging Face checkpoints or train your own architecture.
| New support | Try it |
|---|---|
| DFlash2 speculative decoding for Qwen3.8-27B | DFlash2 recipe and benchmarks |
Measured on one RTX 5090 with the RedHat Qwen3.8-27B INT4 target, shared INT8 vocabulary heads. DFlash2 verifies eight positions (seven draft tokens); native MTP uses three draft tokens:
| Decoding mode | Code tok/s | English tok/s | Translation tok/s |
|---|---|---|---|
| Ordinary greedy | 85.8 | 85.9 | 85.4 |
| Native MTP, 3 drafts | 188.7 | 140.7 | 181.5 |
| DFlash2, BF16 drafter | 223.6 | 140.1 | 212.5 |
| DFlash2, INT8 drafter with packed projections | 239.8 | 139.6 | 221.0 |
Median warmed decode throughput over three runs per fixture; batch-one greedy, 64,000-token context capacity, 2,048-token output cap. Speed depends on proposal acceptance and workload. See the recipe for settings, supported scope and numerical limitations.
DFlash2 output is not guaranteed bit-identical to single-token decoding; these speed measurements are not a model-quality evaluation.
A local workspace, included
Chat with text and images, translate documents, extract OCR Markdown, and ask questions over a local document collection. Watch GPU usage and run a warmed benchmark from the bundled browser UI, with no frontend build step.
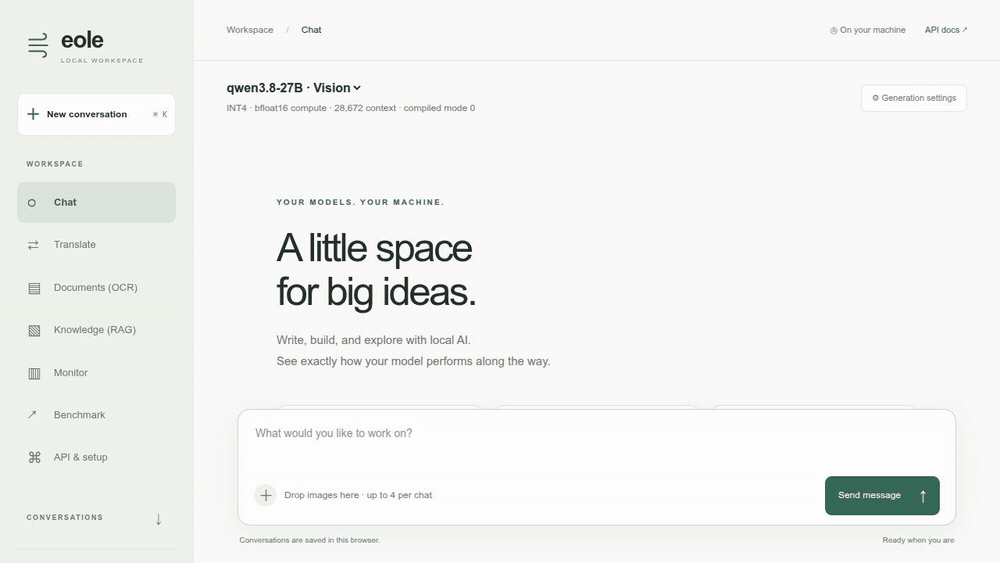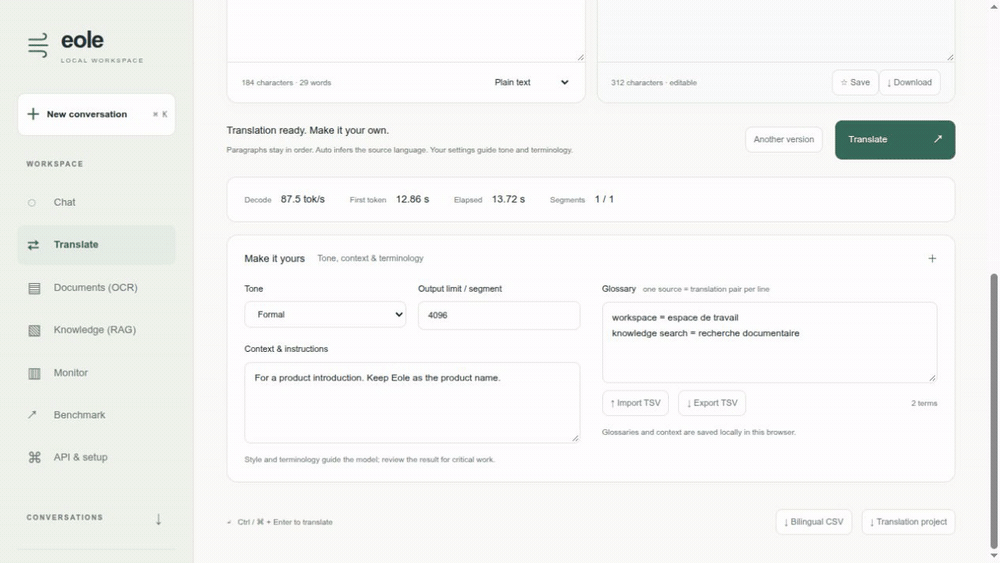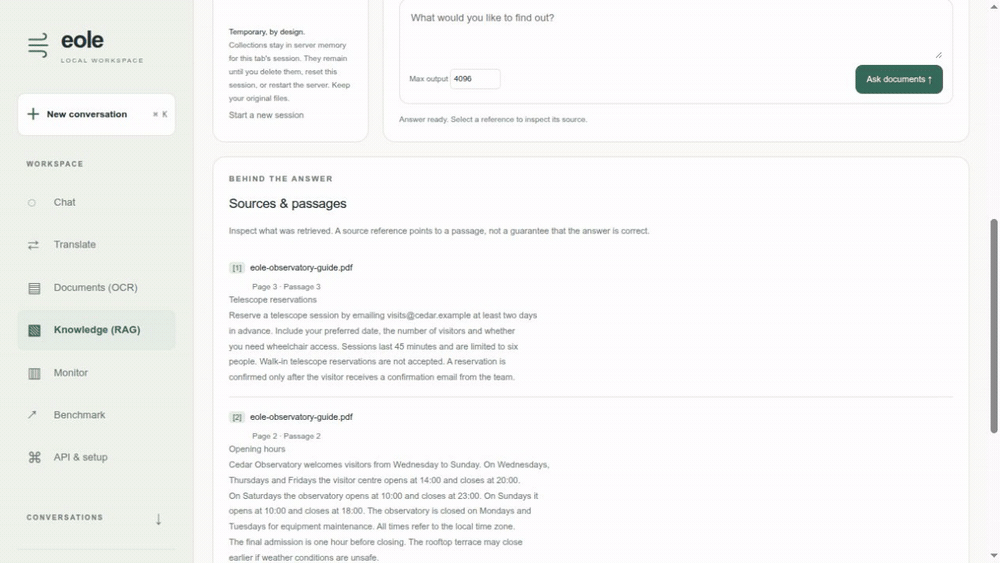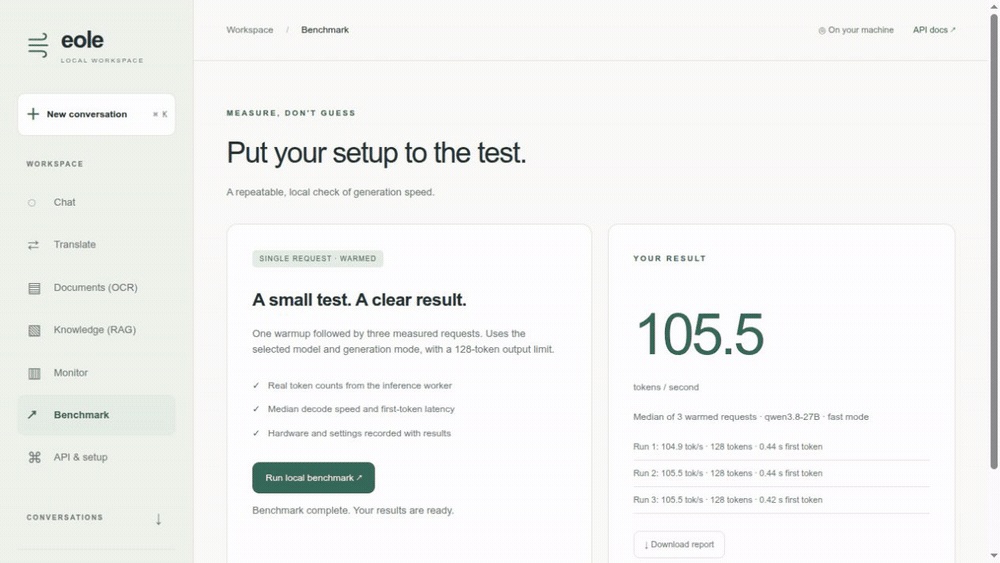
Watch the 39-second MP4 tour · Chat workspace · Hy-MT2 translation workspace · Knowledge (RAG)
The edited tour uses real local results: RedHat Qwen3.8-27B INT4 for visual chat, RAG answers and benchmarking, Hy-MT2-7B for translation, and DeepSeek-OCR for page extraction. The complete workspace menu stays visible. Model loading and compilation waits are omitted; the displayed generation measurements come from Eole's inference worker on an RTX 5090. Benchmark numbers measure post-first-token decode speed and depend on the prompt, settings and hardware.
Latest: 0.6.7
This patch aligns server startup warmup with the workspace default: when available, DFlash2/INT8 is prepared before readiness, avoiding a reload and compilation on the first default Chat request. Missing/incompatible drafters retain native startup settings.
The workspace includes DFlash2 decoding for Qwen3.8-27B and controls for Off/MTP/DFlash2 with separate drafter and vocabulary-head precision. Generation settings open by default, and Chat allows up to 16,384 output tokens. The expanded benchmark compares code, English and translation across six decoding profiles, with warmups, measured results and JSON export. RunPod automatically downloads and verifies the pinned drafter alongside the pre-converted showcase models.
Eole supports PyTorch >= 2.14.1 and < 2.15. The refreshed Docker defaults use PyTorch 2.14.1 with CUDA 13.2. Start with the workspace UI, Qwen3.8/MTP recipe, or Docker guide. See the changelog for release details and remaining limitations.
Browser-based Chat, translation and OCR on a rented GPU. See the
RunPod quick start for password setup, GPU choices and
the required persistent-volume attachment. The 0.6.7 deployment
uses prebuilt GPU kernels and pre-converted public Eole checkpoints. Maintainers
publish the new images and update the public template before the button selects
this release.
Choose your workflow
| I want to… | Start here |
|---|---|
| Run a supported HF model without a separate conversion step | Direct HF inference |
| Deploy an authenticated Chat, translation and OCR workspace on a rented GPU | RunPod deployment recipe |
| Chat with a local LLM in your browser | Local workspace UI |
| Translate through a web interface: text, terminology, subtitles, and documents | Hy-MT2 translation workspace |
| Try Qwen3.8-27B with MTP speculative decoding | Qwen3.8 and MTP |
| Try DFlash2 speculative decoding with Qwen3.8-27B | DFlash2 recipe or workspace controls |
| Use Codex with a locally served Qwen model | Codex Responses API |
| Use Claude Code with a locally served Qwen model | Claude Code endpoint |
| Ask questions about your documents with sources | Local Knowledge / RAG workspace |
| Chat with images in the browser | Qwen vision Chat workspace |
| Try Qwen3.5 text and image inputs | Qwen3.5 |
| Train a translation model | WMT17 |
| Translate with a pretrained multilingual model | NLLB |
| Generate text with Mistral | Mistral |
| Fine-tune an LLM | Llama2 LoRA |
| Fine-tune with a scorer reward | REINFORCE |
| Score translations or use neural metrics during training | COMET, KIWI, XCOMET, and MetricX |
| Extract scanned PDFs through a web interface | DeepSeek-OCR / HunyuanOCR Documents workspace |
| Extract text from images and documents | HunyuanOCR or DeepSeek-OCR |
| Transcribe audio | Whisper |
| Train a language model from scratch | WikiText-103 or FineWeb |
| Evaluate model quality or inference speed | LiveCodeBench coding, MMLU, model validator, or benchmarks |
Browse the full recipe index for more workflows.
Quickstart: serve a small chat model
Run from the repository root in a Python environment with a compatible CUDA PyTorch installation and an NVIDIA GPU. See installation for requirements and optional kernels.
git clone https://github.com/eole-nlp/eole
cd eole
python -m pip install -e . --no-build-isolation
export EOLE_MODEL_DIR="$PWD/models"
mkdir -p "$EOLE_MODEL_DIR"
eole convert HF --model_dir Qwen/Qwen3.5-0.8B \
  --output "$EOLE_MODEL_DIR/qwen3.5-0.8B"
eole serve -c recipes/server/serve.example.yaml --host 127.0.0.1
In a second terminal:
curl --fail-with-body http://127.0.0.1:5000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{"model":"qwen3.5-0.8B","messages":[{"role":"user","content":"Explain machine translation in one sentence."}],"max_tokens":128,"temperature":0}'
The response contains the generated text in choices[0].message.content.
Interactive API documentation is available at http://127.0.0.1:5000/docs.
The server recipe explains streaming and the supported API formats.
Features
- Training and fine-tuning: Transformer encoder, decoder, and encoder-decoder architectures, RNN encoder-decoder models, LoRA, quantized fine-tuning, dynamic data transforms, tensor parallelism, and mixed or pure BF16 training.
- Efficient inference: FlashAttention KV caching, CUDA and Triton kernels,
fused projections, quantized dense and MoE inference, chunked prefill, prefix
caching, and optional
torch.compile/ CUDA graphs. Availability depends on model, hardware, installed kernels, and configuration. - Multi-token prediction: Auxiliary MTP heads for decoder-only training and native speculative decoding for compatible checkpoints, including Qwen3.8-27B. Current inference support is text-only, single-sequence, deterministic greedy decoding; unsupported configurations fall back to ordinary decoding.
- Serving: FastAPI server with native inference, OpenAI-style chat completions, and Anthropic-style Messages endpoints, including tool-use handling.
- Evaluation: BLEU, chrF, TER, perplexity, native COMET/KIWI/XCOMET and MetricX scorers, custom scorer modules, and scorer-based early stopping.
- Reinforcement learning: On-policy REINFORCE with registered scorer rewards, batch-mean baselines, and an optional frozen reference-model KL penalty. DPO, GRPO, and PPO are planned, not implemented.
Supported Hugging Face model families
| Family / task | Examples and notes |
|---|---|
| Qwen | Qwen, Qwen2, Qwen3 (including MoE); Qwen3.5 text/vision; Qwen3.8-27B with MTP |
| Gemma | Gemma3 text/image and Gemma4 support |
| Mistral | Mistral, Mixtral, Mathstral, and supported multimodal / Ministral variants |
| Llama and Phi | Llama3.x and Phi2/3 |
| Translation | Hy-MT2 workspace; EuroLLM, NLLB, and Tower model recipes |
| OCR and vision | HunyuanOCR, DeepSeek-OCR, Pixtral, and supported vision-language checkpoints |
| Speech | Whisper |
| Translation scoring | COMET, COMET-KIWI, XCOMET, MetricX, and MetricX-QE |
Support is architecture-specific; this table does not imply every checkpoint, quantization format, or modality in a family is supported. Consult the relevant recipe and converter for the exact configuration. Supported HF checkpoints can also be used directly for inference; conversion creates a reusable Eole artifact.
Performance and reproducibility
See the inference benchmarks for example scripts and historical results (with incomplete environment metadata), and the compilation guide for
torch.compile configuration. Separate compilation/warmup from repeated warm
runs. Throughput depends on model, precision, prompt length, generation length,
and batch size; benchmark results are not a universal ranking of engines.
The MTP recipe includes a baseline comparison and acceptance diagnostics. GPU speedup and production BF16/quantized token parity must be measured on the chosen checkpoint.
Installation
From source
- Python >= 3.11 (current CI uses Python 3.12).
- PyTorch >= 2.14.1 and < 2.15, with a CUDA build compatible with your GPU and driver.
- To compile CUDA extensions: the CUDA toolkit (
nvcc), a compatible C++ compiler, and the build dependencies below. The CUDA runtime bundled with PyTorch alone does not providenvcc.
Install CUDA-enabled PyTorch first in your chosen environment, then run from the repository root:
python -m pip install "setuptools<69" wheel packaging ninja psutil
python -c 'import torch; print(torch.__version__, torch.version.cuda); print("GPU available:", torch.cuda.is_available())'
nvcc --version
MAX_JOBS=2 python -m pip install -e . --no-build-isolation
setup.py builds Eole's eole._ops CUDA extension, including normalization,
rotary embeddings, activations, and Marlin quantization kernels. It enables
the extension when PyTorch is installed and a GPU is visible, or when an explicit
TORCH_CUDA_ARCH_LIST is provided for a GPU-less CUDA-toolkit build. Official
Docker builds use the latter to bundle multi-architecture ops; see
Docker instructions.
--no-build-isolation lets the build use that PyTorch installation. MAX_JOBS
limits compilation memory use; increase it if your machine has sufficient RAM.
Build kernels for running directly from a clone
If your environment already contains Eole's Python dependencies and you prefer to run scripts without installing the package, build the extension in place:
# Run from the repository root, with CUDA-enabled PyTorch and build tools above.
MAX_JOBS=2 python setup.py build_ext --inplace
export PYTHONPATH="$PWD${PYTHONPATH:+:$PYTHONPATH}"
python -m eole.bin.main --help
This builds eole/_ops*.so; it does not install Python dependencies or the
eole console command. Use python -m eole.bin.main in place of eole in recipes.
Rebuild after changing PyTorch, CUDA, Python, or extension sources. The current
build targets the visible GPU's compute capability; it is not a universal wheel
for every GPU architecture. A successful command on a CPU-only environment may
skip the extension entirely. Check it in the GPU environment:
python -c 'import torch; from eole import _ops; assert torch.cuda.is_available(); print("Eole CUDA extension loaded")'
FlashAttention and hybrid-attention kernels
Install these separately in the same Python environment. FlashAttention is
optional for the small-model quickstart, which uses self_attn_backend: pytorch.
For recipes selecting self_attn_backend: flash, follow the
FlashAttention installation requirements:
MAX_JOBS=2 python -m pip install flash-attn --no-build-isolation
python -c 'from flash_attn import flash_attn_func, flash_attn_with_kvcache; print("FlashAttention interfaces loaded")'
Use a release or wheel compatible with your GPU, Python, PyTorch, and CUDA versions. The Qwen3.8 measurements used FlashAttention 2.8.3; installing a newer package alone does not reproduce that environment.
The Linux PyTorch 2.14.1 wheel requires Triton 3.8.x; the Docker image pins 3.8.0.
For Qwen3.5/Qwen3.8 fast gated-delta computation, install
FLA kernels (fla-core):
python -m pip install "fla-core==0.6.0"
python -c 'from fla.ops.gated_delta_rule import chunk_gated_delta_rule, fused_recurrent_gated_delta_rule; print("FLA gated-delta interfaces loaded")'
Eole also supports the separate CUDA convolution package:
MAX_JOBS=2 python -m pip install causal-conv1d --no-build-isolation
When causal-conv1d is absent, Eole can use FLA's convolution implementation;
without either, it has a PyTorch fallback. FLA uses Triton kernels compiled at
runtime. Import checks confirm availability, not kernel execution or backend
selection; inspect the recipe's backend diagnostics during a GPU run. INT4
Marlin recipes require Eole's compiled CUDA extension.
Install other optional task dependencies as needed:
python -m pip install -r requirements.opt.txt
Use HF_TOKEN with --token "$HF_TOKEN" for checkpoints requiring Hugging Face
authentication. See individual recipes for model-specific requirements.
Docker
Requires Docker, a compatible NVIDIA driver, and the NVIDIA Container Toolkit.
Use a published image or build an image from your checkout (the tested default is PyTorch 2.14.1 / CUDA 13.2). Images include the Chat, Translate, Documents and Knowledge dependencies. The Docker guide covers GPU prerequisites, local builds, CUDA kernels, model/data mounts, YAML inference and training, and serving an API endpoint.
Release images contain that release's features; use a current checkout image for newer features such as MTP. Eole's CUDA extension must be built with GPU access, which a normal Docker image build does not provide.
Documentation and contributing
Use Discussions for questions and feature proposals, and Issues for bugs.